Phone:(+1) 312-698-3083
Email:
info@wappnet.ai

Introduction
Every enterprise AI conversation eventually reaches the same fork: write better prompts, retrieve external data at runtime, or retrain the model itself. Deciding between RAG vs fine-tuning vs prompt engineering trips up even experienced technical teams, because all three promise a smarter, more accurate AI system, yet they solve fundamentally different problems. Gartner predicted in 2023 that more than 80% of enterprises would be using generative AI APIs or deploying GenAI-enabled applications in production by 2026, up from under 5% in 2023 (Gartner, 2023). That shift has made the customization decision unavoidable for CTOs, CIOs, and product teams building real systems, not demos. Here’s what each approach actually does, when to use it, and when combining them makes sense.
Quick answer: Use prompt engineering when the model needs better instructions, not new knowledge. Use RAG when it needs access to current, private, or frequently changing information. Use fine-tuning when it needs consistent, specialized behavior at scale. Combine RAG and fine-tuning when a system needs both proprietary knowledge and specialized behavior.
Key Takeaways
- Prompt engineering shapes behavior through wording alone, with no training data or infrastructure needed and the fastest way to test an idea.
- RAG connects a model to external knowledge at inference time, ideal for private or frequently updated information.
- Fine-tuning changes the model’s parameters, best for consistent tone, specialized tasks, or high-volume repeated workflows.
- RAG and fine-tuning solve different problems and aren’t interchangeable; choose based on whether you need knowledge or behavior change.
- Mature AI systems often combine all three, but added complexity should match actual requirements, not novelty.
- Start with prompt engineering, add RAG when knowledge grounding is the gap, and fine-tune only when specialized behavior is the bottleneck.
18 minute(s) read
October 9, 2026
Table of Contents
- RAG vs Fine-Tuning vs Prompt Engineering: What’s the Difference?
- When Should You Use Prompt Engineering?
- When Should You Use RAG?
- When Should You Fine-Tune an AI Model?
- RAG vs Fine-Tuning: Which Is Better?
- Can You Combine RAG, Fine-Tuning, and Prompt Engineering?
- Which Approach Fits Your Use Case?
- Conclusion
- Frequently Asked Questions
RAG vs Fine-Tuning vs Prompt Engineering: What’s the Difference?
All three techniques customize how a large language model (LLM) behaves, but each one intervenes at a completely different point in the system.
Prompt Engineering
Prompt engineering means designing the instructions, examples, and context you feed into an existing model without touching its underlying parameters. You shape behavior through wording alone: specifying a role, a format, or a reasoning process. It works with any model, deploys instantly, and costs nothing beyond API usage.
RAG
Retrieval-Augmented Generation (RAG) retrieves relevant information from an external source (a database, document repository, or vector store) and inserts it into the prompt at inference time. The model’s weights never change; instead, it answers using facts it wasn’t originally trained on, which is why RAG is the standard approach for grounding responses in private or frequently updated data.
Fine-Tuning
Fine-tuning adjusts a model’s internal parameters using labeled, domain-specific training data. Instead of feeding context at runtime, you’re teaching the model new patterns, tone, or task behavior that persist across every future request without repeating instructions.
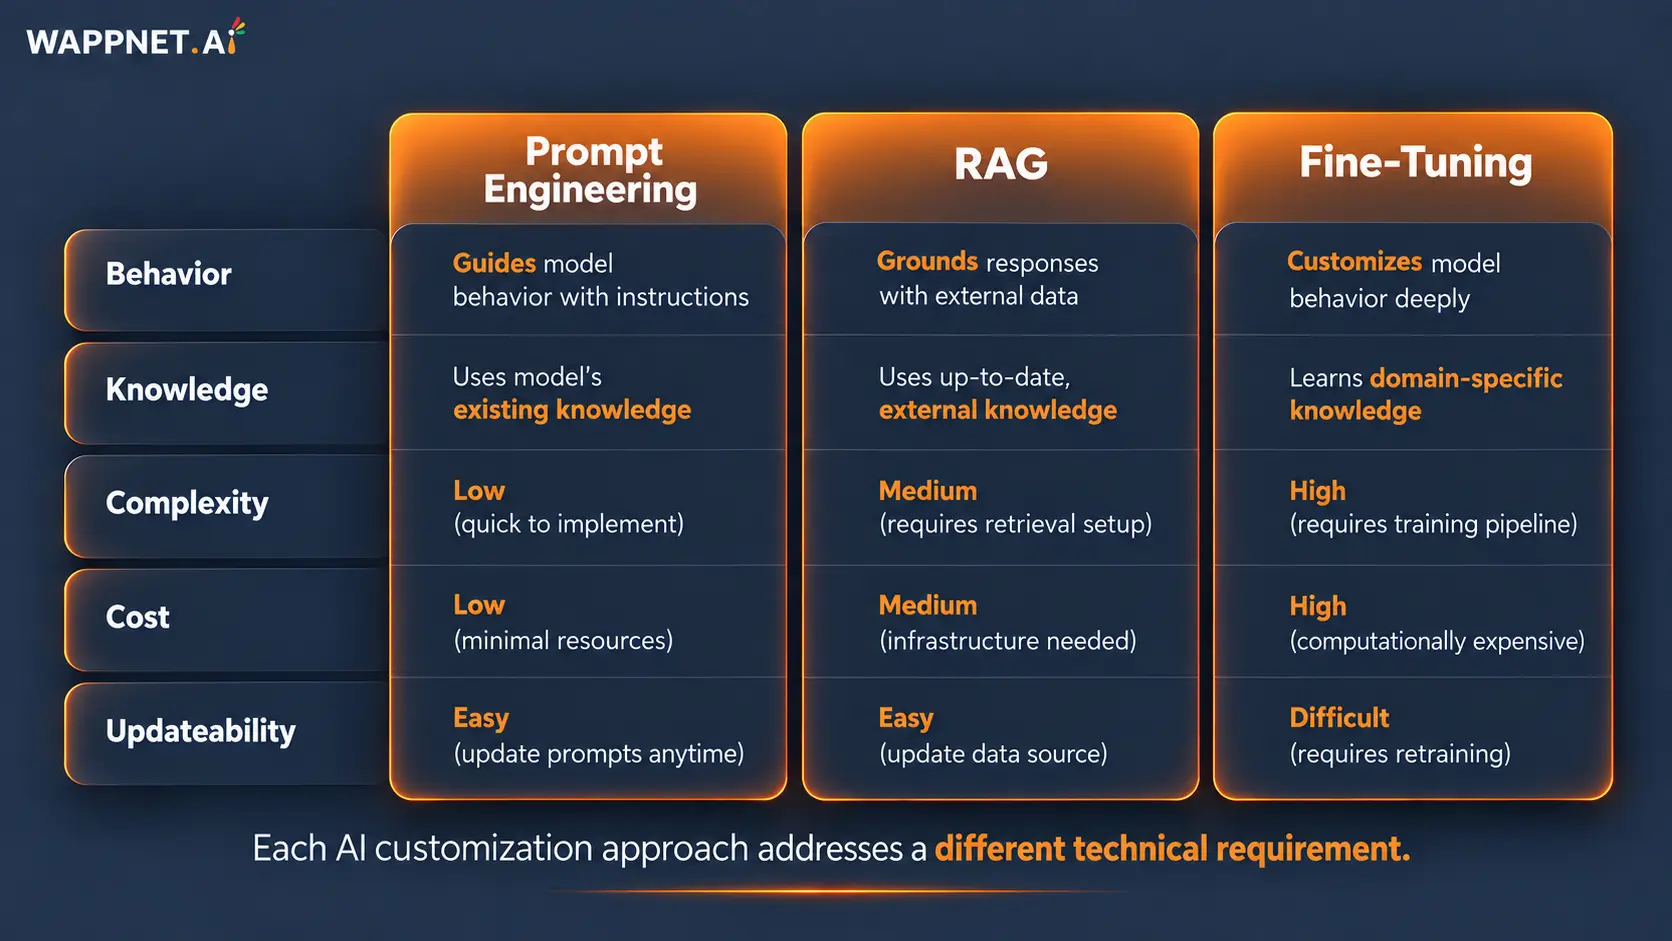
| Factor | Prompt Engineering | RAG | Fine-Tuning |
|---|---|---|---|
| Changes model weights? | No | No | Yes |
| Uses external knowledge? | No (context window only) | Yes, retrieved at query time | No (knowledge is baked in during training) |
| Best for | Instructions, tone, structured output | Current or private knowledge, citations | Consistent behavior, specialized tasks |
| Implementation effort | Low (hours) | Moderate (days to weeks: retrieval pipeline, vector DB) | High (weeks to months: data prep, training, evaluation) |
| Cost | Low (prompt/token costs only) | Moderate (embeddings, vector database, retrieval infra) | High (compute, curated datasets, retraining cycles) |
| Updating knowledge | Manual, per prompt | Update the index or knowledge base anytime | Requires retraining or an additional fine-tuning run |
| Domain-specific behavior | Limited, prompt-dependent | Indirect, via retrieved content | Strong, built into model responses |
| Accuracy/control | Moderate, prompt-dependent | High for factual grounding; reduces hallucination | High for task-specific consistency |
| Typical use cases | Classification, structured output, prototyping | Customer support, internal search, knowledge bases | Brand voice, specialized workflows, compliance-tone tasks |
When Should You Use Prompt Engineering?
Prompt engineering is usually the simplest starting point, and often the only step needed. Reach for it when you need to change response format (JSON, bullet points, tables), improve instruction clarity, apply role-based behavior (“respond as a compliance officer”), enforce structured outputs for downstream systems, run lightweight classification, or prototype an idea before committing engineering resources. Because it requires no infrastructure and no training data, it’s the fastest way to validate whether a use case even needs a heavier approach.
When Should You Use RAG?
Use RAG when the model needs access to information that is private, proprietary, or changes too often to bake into training data: internal documentation, product catalogs, support tickets, policy documents, or a live AI knowledge base. RAG lets you update the underlying content without retraining anything; you simply refresh the index.
Example: A mid-size SaaS company builds an internal support assistant that answers employee questions about HR policy and product configuration. Because policies change monthly, RAG lets the assistant pull from the current document set every time, instead of giving outdated answers baked in from a training run months earlier. Wappnet.ai’s RAG as a Service approach is built around exactly this pattern: connecting LLMs to enterprise data sources without a retraining cycle.

When Should You Fine-Tune an AI Model?
Fine-tuning earns its cost when prompting and retrieval alone can’t produce consistent, specialized behavior: a fixed brand voice across thousands of interactions, domain-specific terminology (legal, clinical, financial), structured response formats that must never drift, or a narrow task performed at high volume where repeating lengthy instructions in every prompt becomes expensive. Gartner projects that by 2027, organizations will run small, task-specific AI models at least three times more often than general-purpose LLMs, largely because specialized models respond faster and cost less to operate at scale.
Fine-tuning is usually unnecessary if better prompting or a retrieval layer already solves the problem. It adds real engineering and maintenance overhead, and unlike a knowledge base, it can’t be updated by simply editing a document. Wappnet.ai’s LLM development services cover this kind of custom model work when the use case genuinely calls for it.
RAG vs Fine-Tuning: Which Is Better?
Neither is universally better; they solve different problems. RAG is generally better for knowledge retrieval and frequently changing information, since it grounds answers in current, verifiable sources and reduces hallucination. Fine-tuning is generally better for changing model behavior, style, or specialized task performance. Our detailed RAG vs Fine-Tuning comparison breaks down cost and architecture differences in more depth if you’re weighing this specific tradeoff.
Can You Combine RAG, Fine-Tuning, and Prompt Engineering?
Yes, and mature enterprise AI systems frequently do. A common production architecture looks like: prompt → RAG retrieval → LLM → fine-tuned behavior/output. The prompt sets the task and role, RAG supplies current or proprietary facts, and a fine-tuned model layer ensures the final response matches a required tone, format, or compliance standard. Enterprises adopting protocols like MCP to connect models with internal tools and data (a trend we cover in our MCP explainer) are essentially formalizing this same layered approach at scale.
The right call is to combine only what the requirements demand. Stacking all three techniques when a well-written prompt would do just adds cost and maintenance without improving outcomes.
Which Approach Fits Your Use Case?
Use Prompt Engineering if:
you mainly need better instructions, formatting, or a quick prototype, and the model already knows what it needs to know.
Use RAG if:
the AI needs current, private, or frequently changing information, and answers must be traceable to a source.
Use Fine-Tuning if:
the AI needs consistent, specialized behavior or task performance that prompting alone can’t hold steady at scale.
Use a Combination if:
you need both proprietary knowledge and highly specialized behavior in the same system, increasingly the norm for production-grade enterprise AI.

Find the Right AI Approach for Your Business
If you’re evaluating which combination fits your systems, Wappnet.ai’s AI consulting and development team can help map the right approach to your data, workflows, and goals.
Conclusion
Choosing between RAG vs fine-tuning vs prompt engineering comes down to one question: are you missing information, or are you missing behavior? Prompt engineering is the fastest test, RAG solves the knowledge problem, and fine-tuning solves the behavior problem, and many production systems eventually need more than one. The stakes are real: McKinsey’s August 2026 State of AI survey found that only about 6% of organizations qualify as “AI high performers” attributing meaningful EBIT impact to AI, even though 80% report improved individual productivity. Architecture choices like the ones in this guide are often what separates the two. Successful enterprise AI implementation starts with matching architecture to the actual business problem, not defaulting to the most complex technique available.
Frequently Asked Questions
What is the difference between RAG and fine-tuning?
RAG retrieves external information at inference time without changing the model, while fine-tuning permanently adjusts the model’s internal parameters using training data. RAG is better for knowledge that changes often or must stay traceable to a source; fine-tuning is better for consistent tone, formatting, or specialized task behavior that needs to hold steady across every response.
Is RAG better than fine-tuning for enterprise AI?
RAG is generally better when enterprise AI needs access to current, private, or frequently updated information, since it avoids retraining and reduces hallucination by grounding answers in real documents. Fine-tuning is better when the priority is consistent behavior or specialized task performance rather than knowledge access, so the “better” choice depends entirely on the use case.
When should you use prompt engineering instead of fine-tuning?
Use prompt engineering instead of fine-tuning when the model already has the knowledge and skill it needs, and the gap is really about instructions: format, tone, or role. It’s faster, cheaper, and reversible, making it the right first step before investing in training data or a retrieval pipeline.
Can RAG and fine-tuning be used together?
Yes, RAG and fine-tuning are commonly combined in production systems. A fine-tuned model handles specialized tone, formatting, or task behavior, while RAG supplies current or proprietary information at query time, giving the system both accurate knowledge and consistent, on-brand responses without retraining every time the underlying data changes.
Is RAG cheaper than fine-tuning?
RAG is typically cheaper to implement and maintain than fine-tuning, since it avoids the compute cost of training runs and the ongoing cost of curating labeled datasets. RAG’s main costs are retrieval infrastructure, like a vector database and embeddings, which are usually lower than the engineering effort fine-tuning requires.
Which AI customization approach should a business choose?
A business should start with prompt engineering to test the use case, add RAG if the model needs current or private knowledge, and fine-tune only if specialized behavior or task performance still falls short. The right approach depends on whether the gap is missing information or missing behavior, not on which technique sounds most advanced.
Ankit Patel
Ankit Patel is the visionary CEO at Wappnet, passionately steering the company towards new frontiers in artificial intelligence and technology innovation. With a dynamic background in transformative leadership and strategic foresight, Ankit champions the integration of AI-driven solutions that revolutionize business processes and catalyze growth.
Related Post
What Is RAG? A Complete Guide to Retrieval-Augmented Generation
September 28th , 2026
RAG vs Fine-Tuning: Which Should You Choose?
July 09th , 2026