Data Preparation, Labeling & Enrichment Solutions
Your CRM has three names for the same company, half your product records are missing a category, and last quarter's support tickets were never labeled consistently enough to use. That's data your team can't fully trust, and it's slowing down your reports, your decisions, and your AI projects. Data Preparation, Labeling & Enrichment solutions from Wappnet.ai clean, label, and enrich your data so your team can finally act on it with confidence.
Why Businesses Invest in Data Preparation, Labeling & Enrichment
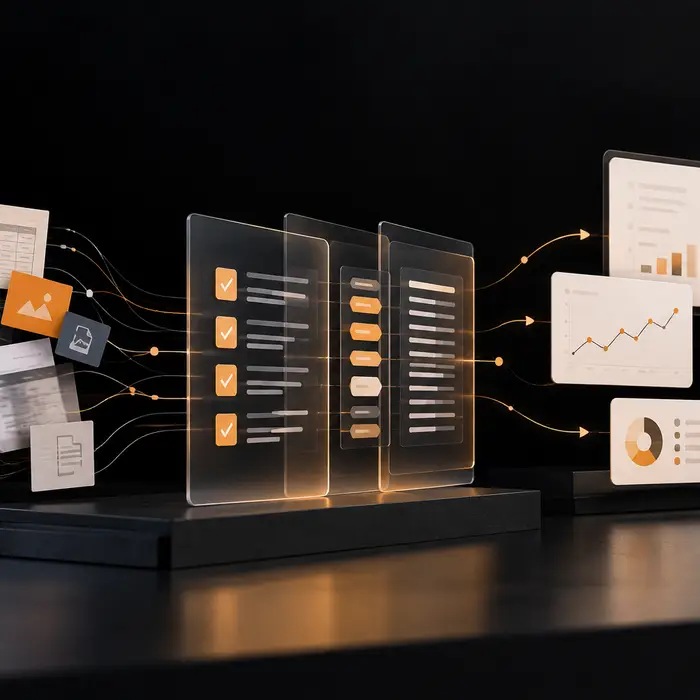
Businesses usually look for better data quality when a recurring problem affects reporting, operations, or AI initiatives. The right approach depends on the issue, the source data, and how the information will be used.
Missing or Inconsistent Fields
Required fields are blank on some records, formatted differently on others, and nobody agrees on which version of a field is the correct one.
Duplicate and Conflicting Records
The same customer, product, or vendor exists multiple times under slightly different names, and nobody is sure which record is authoritative.
Different Formats Across Source Systems
Dates, currencies, addresses, and categories are structured differently depending on which system a record came from, breaking anything that tries to combine them.
Unlabeled Data Needed for Machine Learning
A machine learning or AI initiative needs labeled examples to learn from, and the raw data on hand has no labels, or labels that were never applied consistently.
Inconsistent Annotation Guidelines
Different reviewers labeled similar data differently because the labeling guidelines were unclear, undocumented, or interpreted differently by each person.
Limited Contextual Information
A record has a name and an ID but little else, making it hard to segment, score, prioritize, or act on without manually looking the rest up.
Data That Fails Validation
Records don’t pass the business rules a downstream system or report expects, and nobody has a consistent way to catch that before it causes a problem.
AI and Analytics Projects Delayed by Data Readiness
A promising analytics or AI initiative stalls because the underlying data isn't clean, labeled, or complete enough to start building on top of it.
What Does a Data Preparation, Labeling & Enrichment Solution Include?
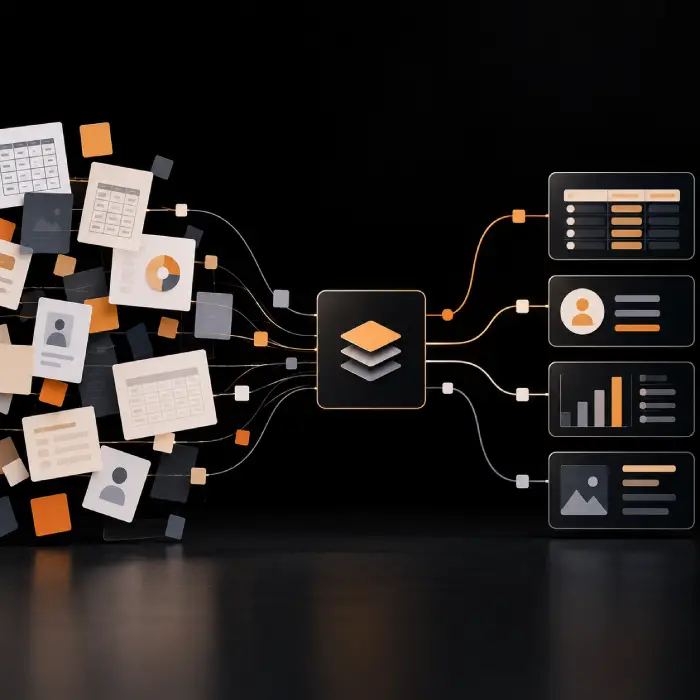
Your data needs to be clean, consistent, and complete before it can support reliable reporting, business decisions, or AI applications. Our data preparation services cover everything from cleaning structured datasets for analytics to preparing unstructured data, such as scanned documents, for downstream use. We build workflows around your data quality requirements and intended outcomes, whether you need a one-time cleanup or ongoing support.
- Profile the data first to find out exactly how incomplete, inconsistent, duplicated, or unlabeled it is, as a baseline measurement.
- Clean and deduplicate records through targeted data deduplication, cutting missing-field and duplicate-record rates.
- Apply data standardization and data normalization so formats, units, and categories mean the same thing across systems.
- Run data validation against your downstream rules, catching issues before they reach a report, dashboard, or model.
- Label and annotate through data labeling services or data annotation services, using human-in-the-loop data labeling, AI-assisted labeling, or both, measured by label agreement and annotation consistency.
- Enrich from approved sources to fill missing context, measured by enrichment coverage.
- Run quality assurance and sampling against defined acceptance criteria, with documentation that keeps the results traceable.
Data Preparation, Labeling & Enrichment Solutions Built for Your Business
Every business has different data challenges, so our data preparation solutions, data labeling solutions, and data enrichment solutions are tailored to the issues that need solving, whether that means cleaning inconsistent records, enriching incomplete datasets, or preparing information for AI applications.
Cleaning Inconsistent Operational Data
Profile a dataset, find where it breaks your systems' rules, and apply one of our data cleansing solutions to fix the problem at its source field.
Standardizing Records From Multiple Systems
Bring dates, currencies, addresses, and category values from different systems into one consistent structure, so a record means the same thing wherever it's used.
Removing Duplicate Records and Resolving Entities
Match records that represent the same customer, product, or vendor under different spellings or identifiers, and apply a clear rule for which version is authoritative.
Enriching Incomplete Customer or Product Records
Add attributes such as firmographic or product category data from approved reference sources, scoped to what the data's intended use actually requires.
Preparing Structured Datasets for Analytics
Clean, validate, and shape a dataset so a reporting or analytics platform can use it directly, without an analyst manually reconciling it first.
Labeling Images, Documents, or Text for AI Applications
Apply defined labeling guidelines to visual, document, or text data through human annotation, AI data labeling with review, or both.
Creating Consistent Training and Evaluation Datasets
Combine training data preparation with careful labeling to build high-quality training datasets, with documented guidelines so labeling stays consistent as the dataset grows.
Validating Data Before Downstream Model Development
Check a dataset against defined acceptance criteria before a machine learning or AI team builds on it, catching problems while they're still cheap to fix.
Improving Data Quality Used in Reporting and Decisions
Reduce missing fields, duplicates, and validation failures in the data that feeds recurring reports, so decisions rest on numbers people actually trust.
Make Your Data More Reliable and Ready to Use
Tell us about your missing fields, duplicate records, labeling requirements, or dataset readiness challenges. We'll help you assess your data quality, identify gaps, and choose the right approach to prepare your data for reporting, analytics, or AI applications.
Works With the Tools You Already Use
Our data preparation and data enrichment services work with the databases, storage, and annotation environments you already run, while our data annotation solutions fit your team’s existing review tools, assessed per system during discovery.
Our Data Preparation, Labeling & Enrichment Process
We take your data from initial assessment to a validated, documented dataset, with quality checks throughout the process. Each stage follows agreed requirements so the final output is ready for its intended use.
- 1
Data & Business Requirement Assessment
We identify the source data, its intended use, quality expectations, and constraints such as privacy or licensing requirements before designing anything.
- 2
Profiling & Issue Discovery
We evaluate completeness, consistency, duplicates, formats, and existing labels to understand the actual condition of the data, not an assumed condition.
- 3
Preparation Strategy
We define cleaning, standardization, transformation, and validation rules matched to the data's intended use, documented so decisions are traceable later.
- 4
Labeling & Enrichment
We apply approved labeling guidelines and relevant enrichment methods, using human annotation, AI-assisted labeling with review, or a combination suited to the task.
- 5
Quality Assurance & Validation
We review outputs against defined acceptance criteria using automated checks, sampling, and human review, and flag what doesn't meet the bar rather than letting it pass through.
- 6
Delivery & Continuous Improvement
We deliver the prepared dataset with documentation of what was done and why, and refine the workflow using feedback and quality findings as your data evolves.
Data Preparation, Labeling & Enrichment: Use Cases
Different teams need reliable data for different reasons. These examples show how better data quality, consistent labeling, and relevant enrichment support everyday business operations and AI initiatives.
Analytics Teams Need Clean, Consistent Data for Reporting
Reports and dashboards draw on data with fewer missing fields, fewer duplicates, and consistent formatting, so stakeholders stop questioning whether the numbers are right, tracked by missing-field and duplicate-record rate in the reporting dataset.
Ecommerce Teams Need Standardized Product Catalogs
Product records from multiple suppliers or channels get consistent categories, attributes, and formatting through product data enrichment, so search, filtering, and reporting work the way customers expect, tracked by catalog field completeness and enrichment coverage.
Operations Teams Need Records Cleaned Before Migration
Records get deduplicated, standardized, and validated before a system migration, so the new system doesn't inherit the old one's data problems, tracked by validation pass rate and duplicate-record rate pre-migration.
Sales and Marketing Teams Need Enriched Account Records
Customer and account records gain context from approved sources through customer data enrichment, supporting segmentation and prioritization without manual lookups, tracked by enrichment coverage across the target account list.
AI Teams Need Documents Labeled for Information Extraction
Document annotation identifies the fields, clauses, or entities a downstream extraction model needs to learn to recognize, following guidelines reviewed for consistency, tracked by label agreement between reviewers on a sampled set.
Computer Vision Teams Need Images Annotated Consistently
Image annotation marks objects, regions, or categories according to defined guidelines, with quality sampling to catch drift between annotators, tracked by annotation consistency across sampled batches.
NLP Teams Need Text Labeled for Model Training and Evaluation
Text annotation assigns categories, sentiment, entities, or other target values to text data, split into training and evaluation sets with consistent guidelines, tracked by inter-annotator agreement on the evaluation split.
ML Teams Need Training and Evaluation Datasets Prepared Together
Machine learning data preparation, labeling, and validation happen as one coordinated workflow, rather than three disconnected efforts that leave gaps between them, tracked by the share of records meeting all defined acceptance criteria.
AI Applications Need Validated Data Before They Go Live
A dataset is checked against defined acceptance criteria before a downstream AI application depends on it, catching data problems before they become application problems. This is data enrichment for AI and data cleaning and preparation working together, not a one-time export, tracked by validation pass rate before handoff to the application team.
Data Cleaning vs. Labeling vs. Enrichment vs. Validation
These four activities are related but not interchangeable, and a single data preparation workflow can combine any or all of them depending on what the data needs.
| Factor | Cleaning & Standardization | Labeling & Annotation | Enrichment | Validation & QA |
|---|---|---|---|---|
Primary purpose | Fix and structure existing data | Assign meaningful labels or target values | Add new attributes or context | Confirm data meets defined requirements |
Typical inputs | Raw or inconsistent records | Raw text, images, documents, or video | Existing records needing more context | Prepared, labeled, or enriched data |
Main activities | Deduplication, formatting, missing-value handling | Guideline-based human or AI-assisted annotation | Matching and appending approved reference data | Rule checks, sampling, acceptance review |
Expected output | Consistent, structured dataset | Labeled dataset with defined categories or values | Dataset with added attributes or context | Pass/fail result against acceptance criteria |
Appropriate use cases | Reporting, migration, general data usability | Machine learning and AI training or evaluation data | Segmentation, scoring, personalization, catalogs | Any step where data must be trusted before use |
Important limitations | Does not add new information, only fixes what exists | Quality depends on clear guidelines and reviewer consistency | Only as reliable as the source it draws from | Confirms data meets rules, not that outcomes will be accurate |
Industries We Help With Data Preparation, Labeling & Enrichment Solutions
Data volume, labeling needs, and regulatory context differ by industry, so this work is scoped per business rather than applied as a single template. Many teams then pair the result with data visualization for day-to-day reporting.
Retail & Ecommerce
Product catalogs standardized and enriched across suppliers and channels, with consistent categories supporting search and merchandising.
Financial Services
Customer and transaction data cleaned and validated with auditability and access controls appropriate to regulatory requirements.
Healthcare & Life Sciences
Operational and administrative data prepared with privacy and compliance requirements considered from the start, not added afterward. Clinical labeling typically requires qualified reviewers.
Manufacturing
Sensor and production data cleaned and validated, and visual inspection images labeled to support quality and defect detection initiatives.
Logistics & Supply Chain
Shipment, inventory, and carrier data standardized across systems to keep operational reporting and tracking consistent.
Technology & SaaS
Product usage and support data cleaned and labeled to support analytics, model training, and internal reporting.
Professional Services
Engagement, billing, and client data consolidated and standardized for consistent reporting across teams and offices.
Insurance
Policy, claims, and underwriting data cleaned and validated, with document annotation supporting claims processing and extraction workflows.
Why Choose Wappnet AI for Data Preparation, Labeling & Enrichment?
Wappnet.ai approaches data readiness as an engineering process aligned with your business goals. We define quality requirements, select suitable preparation and annotation methods, and validate the results before your team uses the data for analytics or AI. Whether you need a data preparation company, a data labeling company, or a data enrichment company, we scope the engagement to your data’s actual condition and our data analytics consulting services pick up once it’s AI-ready data your team can build on.
- Start with business-driven requirement planning before picking a cleaning, labeling, or enrichment method.
- Define quality rules and acceptance criteria around how the data will actually be used.
- Decide where automation fits and where human review is necessary, rather than defaulting to either.
- Apply consistent, documented labeling guidelines and taxonomies that hold as a dataset grows.
- Validate outputs against defined acceptance criteria before calling a dataset ready.
- Document decisions and lineage so your team isn’t dependent on us to understand what was done.
- Support downstream analytics and AI readiness alongside our RAG, LLM development, and responsible AI development practices.
Real-World Data Preparation, Labeling & Enrichment Solutions We've Delivered
See how data-driven organizations leverage automated data cleaning, specialized labeling, and enrichment to power models and analytics.
Omnichannel Product Catalog Standardization & Enrichment
Cleaned, deduplicated, and enriched over 2M product SKUs from 40+ suppliers with taxonomy mapping, reducing search bounce rates by 35%.
High-Precision Document Labeling for Financial Extraction
Prepared and annotated 50,000+ complex loan contracts and bank statements with 99.4% inter-annotator agreement for an automated OCR and LLM pipeline.
Computer Vision Dataset Preparation for Defect Detection
Annotated and validated 100,000+ high-resolution manufacturing sensor images with bounding boxes and defect classes to train real-time edge AI models.
Prepare Your Data for Better Business Decisions
Not sure whether your data is ready for reporting, analytics, or AI? We'll help assess its current quality, identify gaps, and outline the next steps based on your goals.
Latest AI Insights & Industry Trends
 RAG
RAG vs Fine-Tuning vs Prompt Engineering: Which Approach Fits Your Use Case?
Compare RAG, fine-tuning, and prompt engineering to explore costs, use cases, and the best approach for enterprise AI.
 AI Copilot
What is an AI Copilot? Use Cases & Build Guide
What is an AI Copilot? Learn how it works, how it differs from AI agents, key use cases, and how to build one for your business.
 RAG
What Is RAG? A Complete Guide to Retrieval-Augmented Generation
Learn what RAG is, how Retrieval-Augmented Generation works, reduces AI hallucinations, and powers smarter enterprise AI.
Frequently Asked Questions
Data preparation is the process of cleaning, structuring, transforming, validating, and organizing raw data so it is suitable for a specific business or analytical purpose, such as reporting, analytics, or machine learning.
Data preparation cleans and structures existing data. Data labeling assigns categories, annotations, or target values to data, often to build or improve machine learning datasets. Data enrichment adds new attributes or context from approved sources. A project may need one, two, or all three depending on the problem, and they are often combined within a single workflow.
Machine learning and AI systems learn from the data they are given, so missing values, inconsistent formats, duplicate records, or unclear labels in that data tend to show up as errors or unreliable behavior in the resulting model or application. Preparation does not guarantee performance, but unaddressed data problems reliably limit it, and more data is not automatically better if it isn't relevant, accurate, or appropriately sourced.
Data labeling, or annotation, is the process of assigning meaningful tags, categories, or values to data, such as marking objects in an image, classifying a block of text, or extracting fields from a document, according to a defined set of guidelines so the results are consistent across the dataset. It is distinct from data classification, which is typically the application of an already-trained model's output rather than the creation of the labels it learned from.
Data enrichment adds attributes, context, or reference information to existing records from approved internal or external sources, such as appending firmographic detail to a company record or standardized category data to a product record, making the dataset more useful without changing what it originally represented. It is different from simply collecting more unverified data, because enrichment draws on sources that have been assessed for reliability and fit.
Missing data is typically addressed through profiling to understand how much is missing and why, then a defined rule for each field: flag it, fill it from another approved source, or leave it blank with a clear reason. Duplicates are typically addressed through matching and entity resolution rules that decide which record is authoritative, which is more complex when records don't share a single consistent identifier across systems.
Human review is generally appropriate when guidelines are ambiguous, when the subject matter requires domain expertise, when the cost of a labeling error is high, or when AI-assisted labels need spot-checking before they're trusted. AI-assisted labeling can reduce manual effort and cost, but it does not remove the need for human review in every case, particularly for sensitive, high-stakes, or edge-case data.
Common measures include completeness (missing-field rate), uniqueness (duplicate-record rate), validity (validation pass rate), consistency across sources, enrichment coverage, and, for labeled data, label agreement or annotation consistency between reviewers. These are evaluation criteria to track and improve over time, not universal fixed targets every business will hit.
Reporting and analytics outputs are only as reliable as the data feeding them, so addressing missing values, duplicates, inconsistent formats, and validation failures tends to make dashboards and reports more trustworthy. It does not guarantee a specific accuracy outcome, since reliability also depends on how the data is analyzed and interpreted downstream.
Data cleaning actively fixes problems in the data, such as correcting formats, filling or flagging missing values, or removing duplicates. Data validation checks data against defined rules to confirm it meets requirements, such as a required field being present or a value falling within an expected range, and flags or rejects records that fail. Validation is often the step that confirms cleaning actually worked, and it is distinct from the broader practice of data governance, which covers ongoing policies, access, and stewardship rather than a one-time check.
Timelines vary significantly based on data volume, how many sources are involved, how much manual versus AI-assisted labeling is needed, the complexity of the labeling guidelines, and existing data quality. A focused cleanup of a single dataset can move faster than a multi-source labeling program with ongoing human review; we provide a realistic estimate after a discovery assessment.
We start with a data and business requirement assessment, profile the data to find quality and labeling issues, define a preparation strategy with clear rules, apply labeling and enrichment using approved guidelines and sources, run quality assurance and validation against acceptance criteria, and deliver the dataset with documentation so your team understands exactly what was done and why.